Opus 5.5 vs Astra 6.2: Which Is Better Value, a Claude or an OpenAI Subscription?
721 h
Claude Ultra for $200
hours of work one agent gets per month, almost around the clock
828 h
ChatGPT Pro for $200
15% more hours. But Astra works slower, so the number of tasks is about the same: 2,219 vs 2,150
3%
cheaper for a typical task on Astra
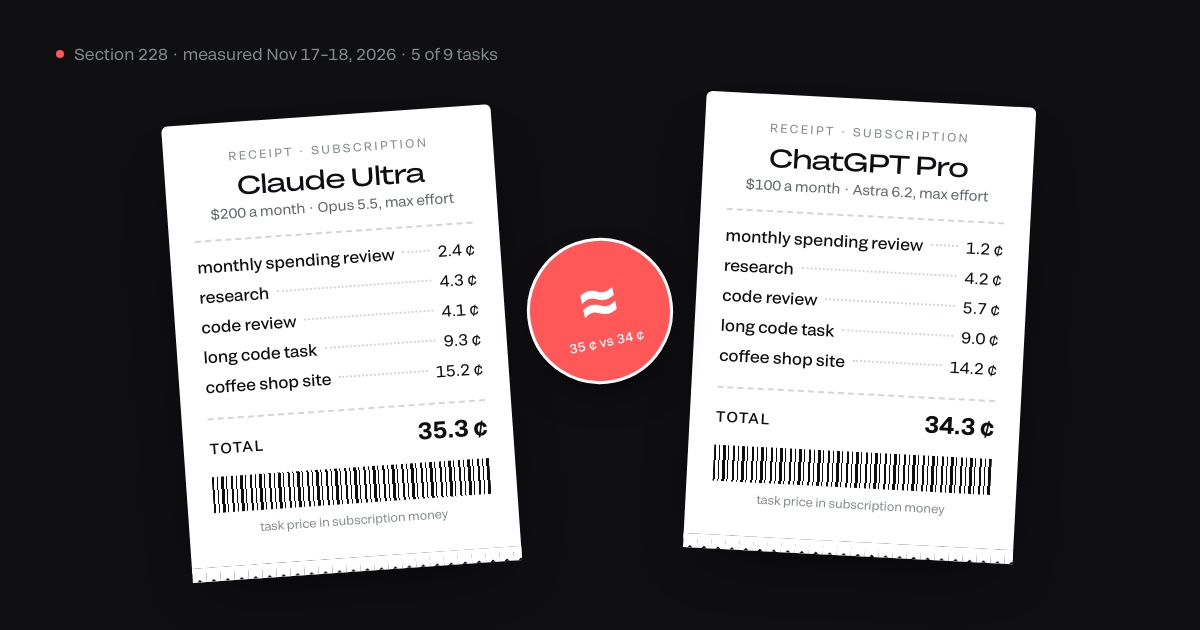
not several times, as people say. All 9 tasks together: 72 cents on Opus, 62 on Astra
24/24
coding runs passed the tests
on both models. Quality from two judges is close: 82% for Opus, 86% for Astra
GPT-6.2 Astra came out on November 17, and chats immediately said it was several times cheaper than Claude. We took our own subscriptions, Claude Ultra for $200 and ChatGPT Pro for $100, and ran 9 real work tasks on them overnight. The result: a typical task on Astra is 3% cheaper, all 9 tasks together 13%. Not several times. For the same $200 you fit about the same number of coding tasks.
Measured by Kirill Pukshto, CEO of Section 228, on November 17–18, 2026.
How we tested
The companies don’t say how much work a subscription includes, only the percentage of the weekly limit. At 23:37 Kirill finished work, and we checked that our other chats were idle so the meter would see only our test. 15 agents worked until the weekly meter ticked twice in a row. Everything they used between the ticks is exactly 1% of the week.
We caught a “clean” 1% of the limit and ran 9 tasks
step 1
15
agents work nonstop while our other chats stay idle
step 2
2 ticks
of the weekly meter in a row: 13 → 14 → 15%. Exactly 1% in between
step 3
$22.8
of work at list price = 1% of a Claude Ultra week. On ChatGPT Pro 1% = 155 credits
step 4
9 tasks
from a spending review to long code, each 2–5 times, both models on max
step 5
2 judges
Opus and Astra review the work blind, not knowing whose is whose
November 17–18, 2026, overnight. Claude Code 2.1.319 and Codex CLI 0.169.0, personal Claude Ultra ($200) and ChatGPT Pro ($100) plans.
How many hours of work a subscription gives
A month has 720 hours. The $200 Claude plan gives one agent 721 hours of work, almost around the clock all month. By our estimate the $200 ChatGPT plan gives 828 hours. But Astra worked 13% slower in our runs, so the number of coding tasks is about the same: 2,219 vs 2,150.
For $200: 721 hours of work on Claude, 828 on ChatGPT
$20
$100
$200
ChatGPT Pro for $500: almost 3 agents around the clock. Claude has no such plan
Hours = agent working time on our 9 tasks ÷ the share of the week they used; median. Hours depend on speed: Astra worked 13% slower in our runs, so it gets more hours for about the same number of tasks. Measured on Claude Ultra and ChatGPT Pro $100, other plans scaled by multipliers. Accuracy ±20%.
| Plan | Price | Agent hours per month | Long coding tasks per month |
|---|---|---|---|
| Claude Pro | $20 | 72 | 215 |
| ChatGPT Plus | $20 | 41 | 111 |
| Claude Max | $100 | 361 | 1,075 |
| ChatGPT Pro | $100 | 414 | 1,109 |
| Claude Ultra | $200 | 721 | 2,150 |
| ChatGPT Pro | $200 | 828 | 2,219 |
| ChatGPT Pro | $500 | 2,071 | 5,547 |
Bottom line: at $100 and $200 ChatGPT gives 15% more hours, but about the same number of tasks. At $20 Claude gives almost twice the hours. Only ChatGPT has a $500 plan.
What one task costs
Task price is its share of the weekly limit converted into subscription money. We measured on Claude Ultra and ChatGPT Pro $100.
All 9 tasks: 72 cents of subscription on Opus and 62 on Astra
| Task | Task price in subscription money | Cheaper |
|---|---|---|
Review a month of spendingeveryday task, 69 lines | Astra, 2× | |
Find 5 booking services for a salonresearch with prices and links | even | |
Code review7 planted bugs | Opus, 1.4× | |
Find a hidden bugonly the symptom given | even | |
Short code, no promptjust the task text | even | |
Short code with a prompt1 failing test of 11 | even | |
Long code task12 failing tests of 31 | even | |
Coffee shop site, no promptmenu, address, booking | even | |
Short code via a pipelineGSD + Superpowers: plan, tests, review | Astra, 1.7× |
Task price = its share of the weekly limit × plan price ÷ 4.3 weeks. Median of 2–5 runs. Accuracy ±20%: “even” means the gap is within the margin. Measured November 17–18, 2026.
Bottom line: Astra is cheaper on 8 of 9 tasks, but noticeably only on the everyday task (2×) and the pipeline (1.7×). Opus is cheaper on code review. A typical task on Astra is 3% cheaper; the 13% across all 9 tasks comes almost entirely from the pipeline. The measurement is accurate to ±20%, so “even” means the gap is within the margin.
Work out your own subscription
Set how many tasks a week you hand to AI and see which plan can take them.
How much of your week will your tasks use
Set how many tasks a week you give to AI. On the right you see how full each plan’s weekly limit gets.
Claude · Opus 5.5
Claude Pro$20
Claude Max$100
Claude Ultra$200
ChatGPT · Astra 6.2
ChatGPT Plus$20
ChatGPT Pro$100
ChatGPT Pro$200
ChatGPT Pro$500
Based on our measurement at max effort. A coding task counts as our long code task, research as finding 5 services with prices, everyday as a spending review. Five-hour windows are not included.
Which one is smarter and faster
We ran each task 2–5 times. Two blind judges, Opus and Astra, reviewed the first copy of each result without being told whose it was. On coding tasks both models passed the tests in all 24 runs.
Quality from two blind judges: 82% for Opus, 86% for Astra
Quality is the average score of two judges out of 10, times 10. The judges did not know whose work it was. Time: median of runs. In bold: the faster one, and the better one when the gap is 5 points or more.
| Task | Opus, min | Astra, min | Opus, quality | Astra, quality |
|---|---|---|---|---|
| Monthly spending review | 5 | 3 | 90% | 75% |
| Research on salon services | 7 | 13 | 80% | 95% |
| Code review, 7 planted bugs | 10 | 17 | 90% | 95% |
| Long code task | 18 | 18 | 87.5% | 85% |
| Coffee shop site, no prompt | 33 | 35 | 65% | 90% |
| Short code, no prompt | 22 | 30 | 80% | 80% |
| Short code with a prompt | 14 | 23 | 80% | 80% |
| Short code via a pipeline | 38 | 27 | 75% | 80% |
| Find a hidden bug | 5 | 6 | 90% | 90% |
Each judge favors its own model: the Opus judge gives Opus 85% and Astra 80%, the Astra judge gives Astra 91% and Opus 79%. That is why there are two judges and we take the average.
We score quality with our own method: each judge rates the work out of 10, we average the two judges and multiply by 10. A gap under 5 points counts as “close”. Opus did better on the spending review: 90% vs 75%, it found all 3 oddities, Astra 2 of 3. Astra did better on research (95% vs 80%, all prices with tax, 2–3 sources each), the site (90% vs 65%), and on review and the pipeline (by 5 points). The other four tasks, the long code task included, came out close.
Bottom line: 82% for Opus and 86% for Astra, a gap under 5 points. Opus was clearly faster on four tasks (research, review, short code with and without a prompt), Astra on two (spending review and pipeline). Astra was measured on release day.
The same site from two models
Code is hard to judge by eye, but a site you see right away. Both models built all 12 menu items, the address and opening hours.
One task, two coffee shop sites
“Build a coffee shop site from menu.json with table booking, check it yourself.” Nothing else, no prompt. The task was in Russian, so the sites are in Russian.
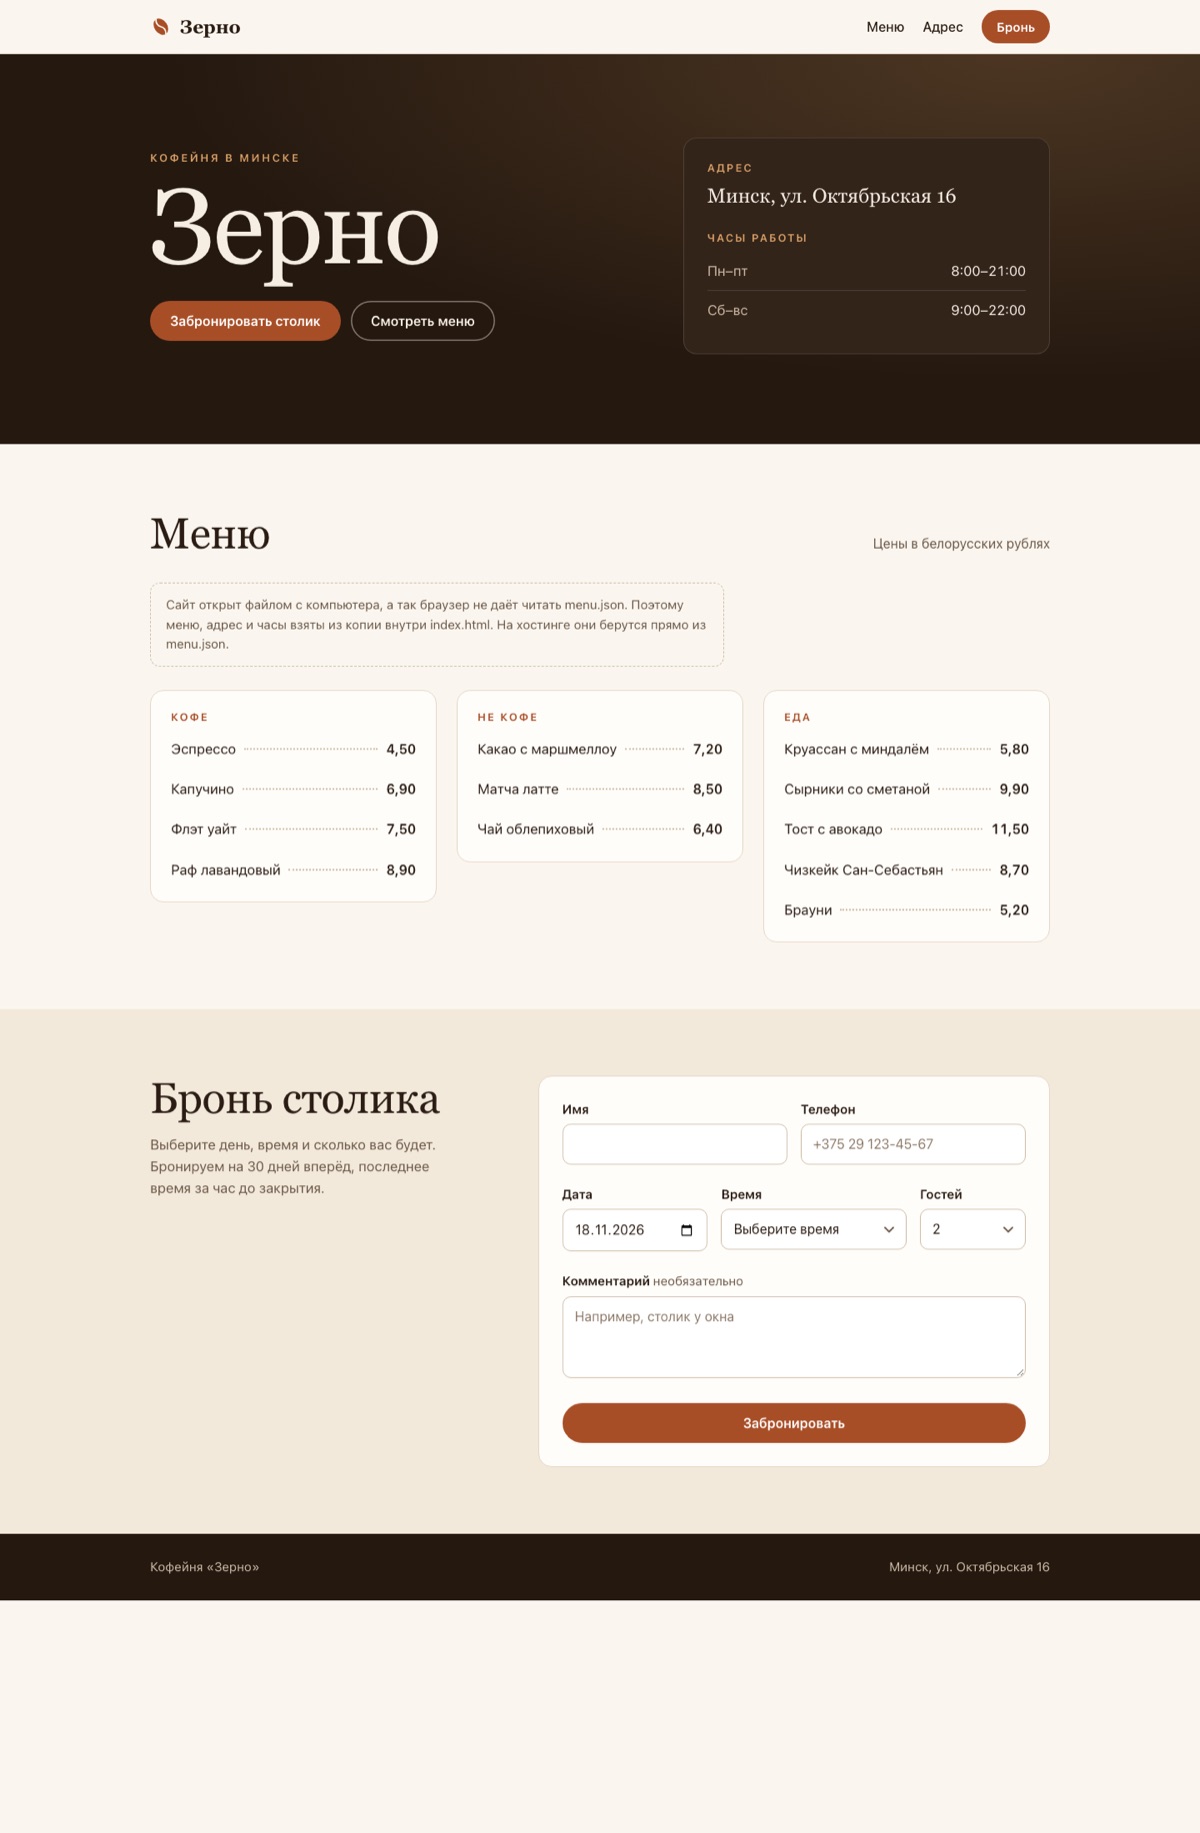
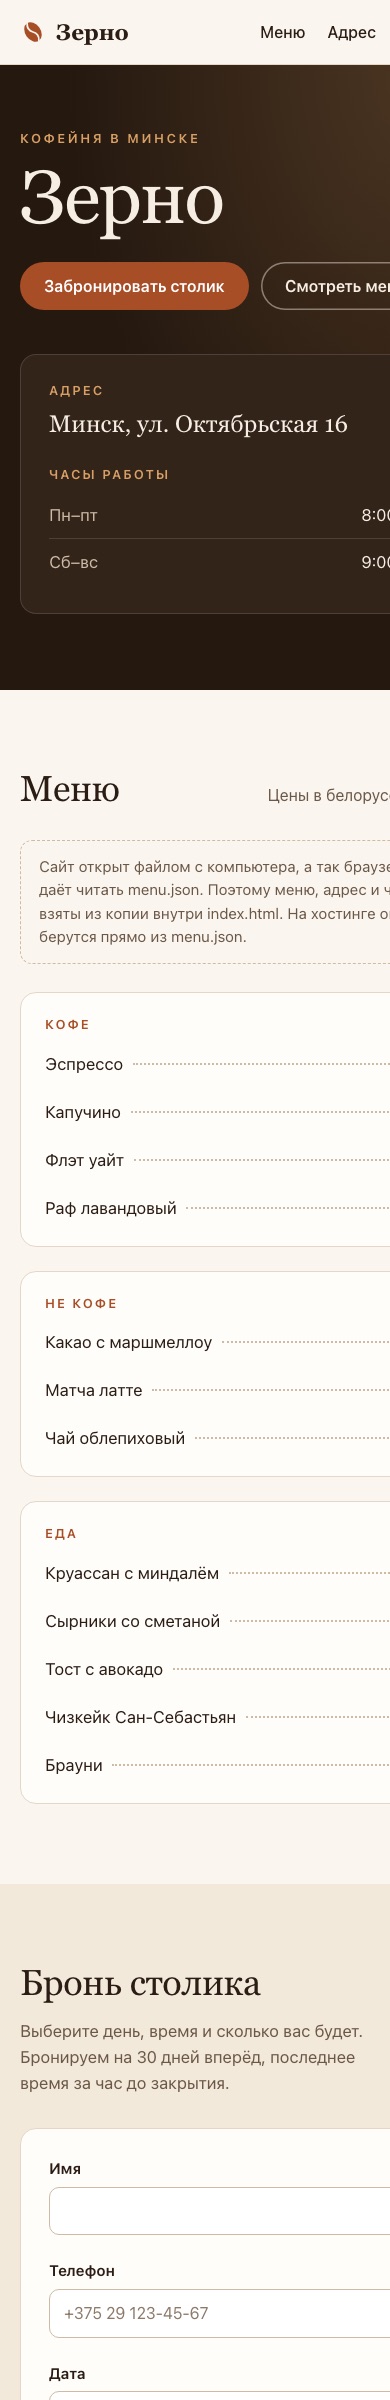
What the judges noticed · 7 and 6 of 10A neat form: booking times only within opening hours. But it tells the guest “booking received”, while the booking goes nowhere.
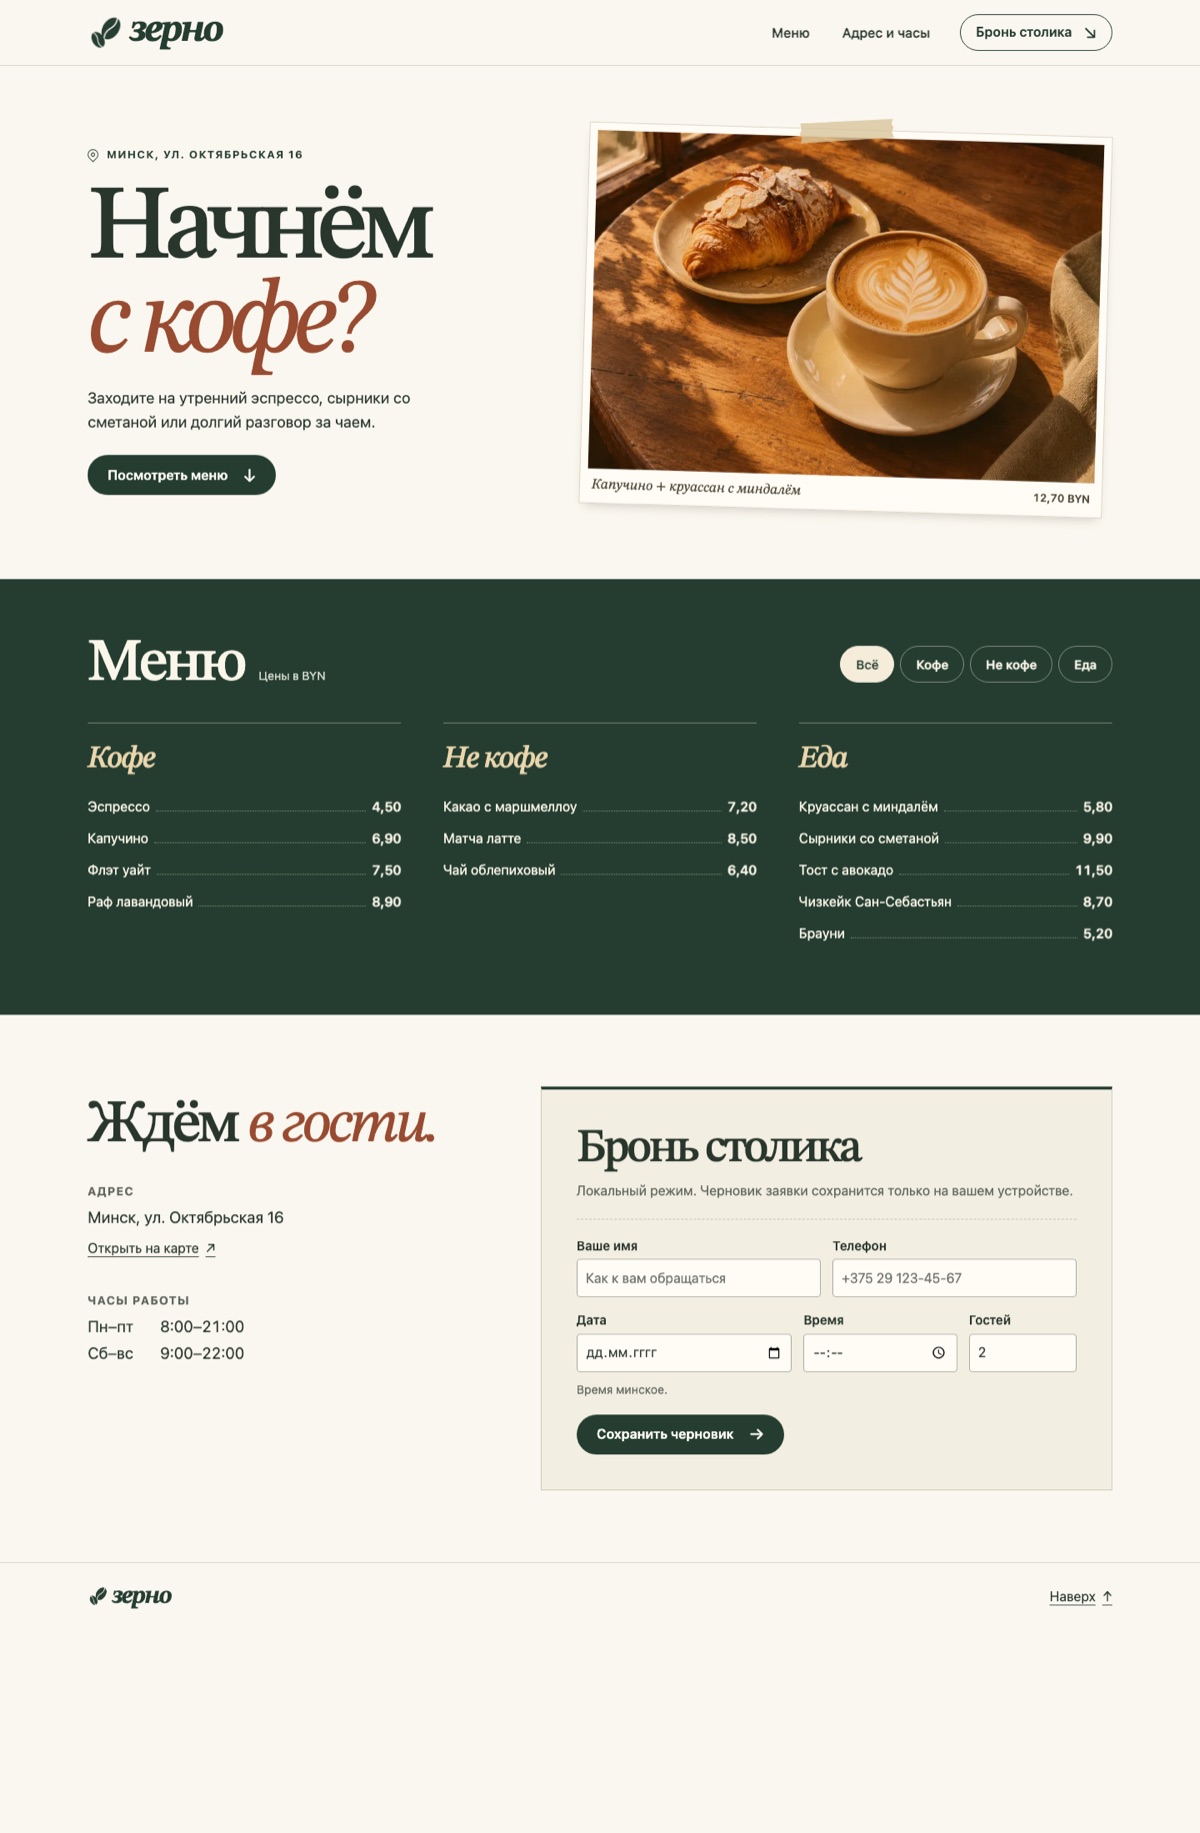
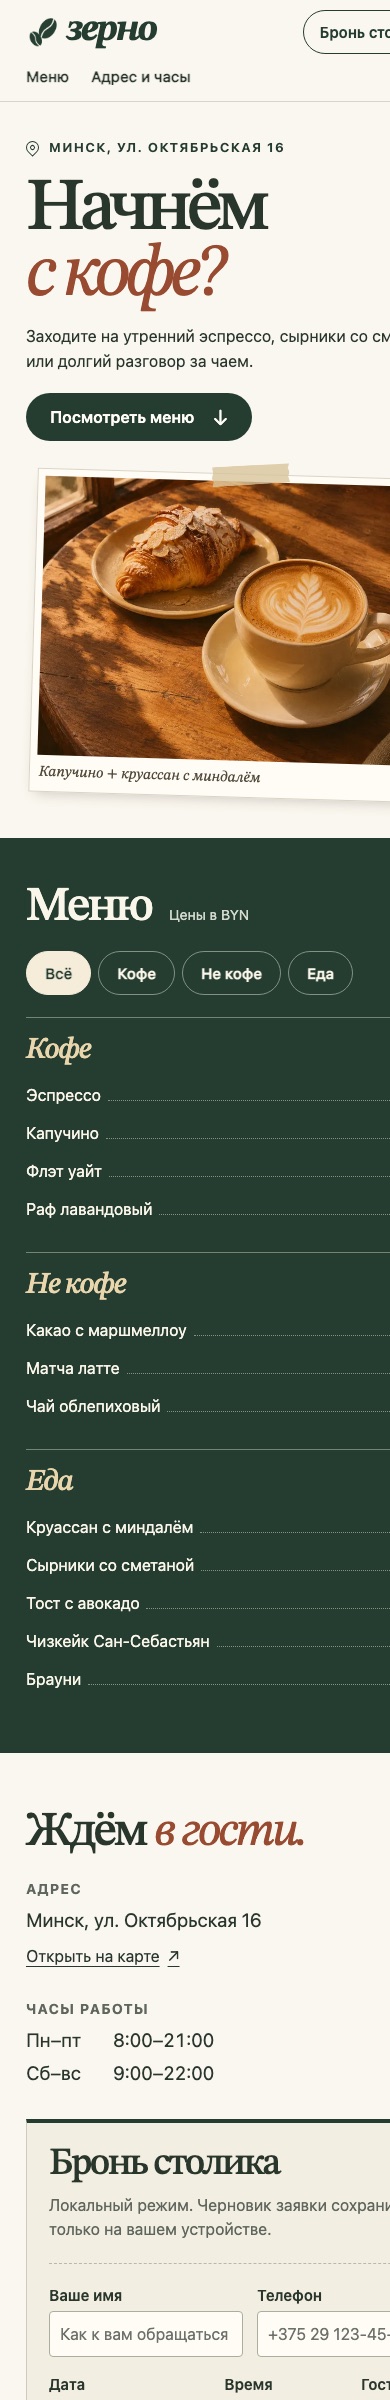
What the judges noticed · 8 and 10 of 10Made its own photo of coffee and a croissant. Without a server it honestly says “draft”, with a server it saves the booking and avoids duplicates.
Why Astra seems several times cheaper
Astra uses 1.6–5 times fewer tokens for the same task. That is where the talk comes from. But both companies charge the limit roughly by the price of tokens, not by their number. Rereading a long conversation is almost free, while new model text is expensive.
We tripped over this ourselves. Overnight the ChatGPT meter went from 61% to 70%, and Claude only from 13% to 21%, although several more of our chats were running in Claude.
“I sense a catch here”Kirill Pukshto, CEO of Section 228, at 1 a.m.
We checked the logs: overnight the chats read 150 million tokens, almost all from cache, and on the meter that is about 3%. As a share of its own plan, Opus really does burn its limit 2 times slower. But its plan also costs $200 instead of $100.
4Mnew text and cache writes
146Mold conversation read from cache
Lots of tokens, few percent
Overnight our Claude chats read 150 million tokens. Almost all of it is old conversation: the model rereads it on every turn, but from cache. At list price that is 20 times cheaper than normal input, and the limit is charged the same way.
of the Ultra week is what those 150M tokens cost. So count the price of tokens, not the tokens
Cross-check on November 18: all chat and test logs for the night against the weekly meter. Price-based forecast 6.8%, meter +6%.
Where you overpay: a pipeline for small fixes
The most expensive line in the table is our own. A short code fix through the GSD + Superpowers pipeline (plan first, then tests, then review) cost three times more on Opus than with a plain prompt: 18.5 cents vs 6.2. Astra got 1.8 times more expensive. For a small fix that way of working turned out to be overpaying; we have not measured it on big tasks yet.
What to buy
- $20 a month: Claude Pro, almost twice the hours of ChatGPT Plus
- $100 or $200: ChatGPT gives 15% more hours, about the same number of coding tasks. Everyday reviews are better on Opus, research and “build it from scratch” on Astra
- need more than $200 gives: ChatGPT Pro for $500, almost 3 agents around the clock. Claude has no such plan
- running many agents at once: the limit runs out in hours. 15 agents use 1% of the week in 8 minutes. Our Ultra also has a five-hour window, and at that pace it runs out in 3–6 hours
How we measured
- Plans: Claude Ultra ($200) and ChatGPT Pro ($100), personal, not business. Tools: Claude Code 2.1.319 and Codex CLI 0.169.0
- Models: Claude Opus 5.5 and GPT-6.2 Astra, both at max effort (Astra in Codex also has ultra, which hands work to helpers on its own; we did not use it). No custom rules, memory or plugins, just the task
- Calibration: 15 agents nonstop until the weekly meter ticked twice in a row. 1% of an Ultra week = $22.8 of work at Anthropic list price, 1% of a Pro $100 week = 155 Codex credits
- Tasks: 9, each run 2–5 times. Task price = its usage at list price ÷ calibration × price of a percent. Hours = working minutes ÷ share of the week, median across tasks
- Other plans via multipliers: Claude’s are official (Max 5× Pro, Ultra 10×); ChatGPT’s are our estimate: OpenAI named 5×, 20× and 25× Plus for Pro at $100, $200 and $500 and doubled the Pro $100 and $500 limits on October 29
- Cross-check: overnight we added up the logs of all chats and tests and compared them with the meters. Forecast for Claude 6.8% vs +6, for ChatGPT 10.1% vs +9. Including the judges’ usage, Claude accuracy is ±20%
- Limitations: one account per company; the meters show whole percentages only; runs of the same task differ up to 2×; the judges saw one copy of 2–5; Astra speed was measured on release day, and hours depend on model speed
FAQ
How many hours of work does a $200 subscription give?
Claude Ultra gives about 721 hours of one agent’s work per month, almost around the clock. By our estimate ChatGPT Pro for $200 gives about 828 hours, but Astra works slower, so the number of tasks is about the same.
Why does the Claude weekly limit run out in two days?
Because of parallel agents. 15 agents use 1% of the week in 8 minutes, so a whole Ultra week is gone in about 13 hours. That is exactly what happened to us in November: we used one and a half weekly limits in a week.
Claude Code or Codex: whose limit runs out first on coding?
As a share of its own plan, Codex on Pro $100 runs out first. In money it is about the same: Pro costs $100, Ultra $200.
Why does a long chat barely use the limit?
The model rereads the old conversation every time, but from cache. At list price that is 20 times cheaper than normal input, and the limit is charged the same way.
Should I pay $100, or is $20 enough?
If AI writes code for you every day, take $100. On $20, Claude gives about 72 hours of agent work per month, ChatGPT about 41.
We’ll work out what AI costs your team
We’ll go through your tasks and pick the plan and model for each, so the limit doesn’t run out by Wednesday.
Get in touchMeasured November 17–18, 2026. We will update it when new models come out or plans change.
Come say hi on social media: Instagram section.228, TikTok @section_228, LinkedIn company/section228